
VLA Robotics on an NPU: How Nota AI Got GR00T N1.7 From 1.6s to 230ms
On September 18, 2026, Nota AI published a detailed account of running NVIDIA’s GR00T N1.7 — a 3-billion-parameter Vision-Language-Action foundation model — on a Qualcomm Dragonwing IQ-9075 NPU board with no GPU, inside a real-time target of 320–400ms per inference cycle. At baseline on that hardware, the model ran at 1,602ms. The final published configuration reached approximately 230ms — a 7x improvement — through five consecutive engineering decisions made over a period of weeks leading up to a live demonstration at a Seoul robotics conference in September 2026. All optimizations were applied without changing the model’s task success rate by more than one percentage point in closed-loop simulation.
The result matters because it establishes, with published numbers from real hardware, that current-generation VLA foundation models can run at robotically-useful latency on NPU SoCs — not on an H100, not on a high-end workstation, but on a palm-sized compute board designed for embedded deployment.
Why NPUs, and Why Now
GPU modules draw significant power and generate heat. For a battery-powered robot operating in a home, warehouse, or clinical environment, those are hard constraints, not inconveniences. In mass production, the cost of the compute board directly determines unit economics. A Qualcomm IQ-9075 NPU SoC integrates control, vision, and communication in a single chip designed for compute-per-watt efficiency. Qualcomm has published a 700-TOPS-class robotics SoC, and Intel has signaled similar moves away from GPU-centric robot compute.
The practical problem Nota faced: every published VLA latency number is an H100 number. The models were built and benchmarked on GPUs. Tooling for moving these models to embedded NPUs was sparse. Nota found almost no existing literature on what to expect during NPU deployment of a VLA model at this scale.
What GR00T N1.7 Actually Is
GR00T N1.7 is NVIDIA’s open reasoning VLA model for humanoid robots, described in detail in arXiv:2503.14734. It uses an Action Cascade architecture with two distinct components. System 2 is a Vision-Language Model that processes image tokens and natural language instructions — the slow, deliberate planning component. System 1 is a Diffusion Transformer that takes the VLM’s output and live robot state and denoises them into precise motor commands in real time — the fast, reactive execution component.
This two-system design is significant for optimization. Each component has different latency requirements and different sensitivity to compression. System 2 needs to plan correctly but does not need to run on every control cycle. System 1 generates motor commands at the control frequency and is the direct latency bottleneck for smooth arm operation.
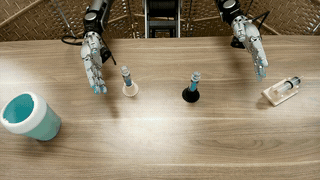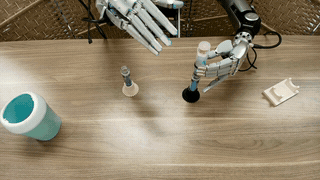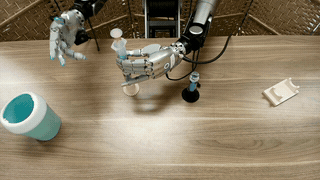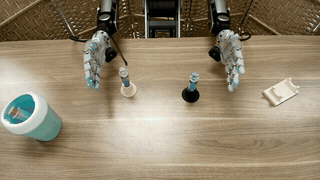
Five Decisions That Reached 230ms
Decision 1 — Build a Custom Runtime Before Touching the Model
When Nota dropped their initial VLA candidate (MolmoAct2) onto the existing on-device inference stack, end-to-end cycle time was 3,681ms. The first discovery was not a model problem: the runtime assigned one model to one NPU, leaving the second NPU on the IQ-9075 completely idle. Nota built NQRR (Nota QNN Robotics Runtime), a robotics-specific inference runtime that distributes a VLA’s compute graph across multiple NPUs in a single process. Combined with three graph-level rewrites — vision encoder restructuring, LLM layer distribution, and action head pre-computation — MolmoAct2’s latency fell from 3,681ms to 1,173.9ms.
Even at 1,173ms, the model was still three times over the 320–400ms real-time bar. A segment-by-segment profile revealed why: eliminating the LLM component entirely, the vision encoder and action head together still exceeded 400ms. The constraint was structural to the model architecture, not runtime-fixable.
Decision 2 — Screen Backbone Candidates on Real Hardware, Not Benchmarks
Nota screened twelve VLA candidates against four structural criteria: suitability for step distillation, temporal caching viability, vision token pruning effectiveness, and baseline latency on the target hardware. They ran five finalists directly on the IQ-9075 board with NQRR and measured. GR00T N1.7 achieved a 7x speedup after optimization within one percentage point of accuracy loss in closed-loop simulation. Critically, it also had the best real-hardware task success rate — 80% on the physical SO-101 arm in manipulation tasks.
The model with the lowest bare latency had the lowest real-hardware task success rate. Nota chose GR00T N1.7 by the combined criterion: latency potential plus physical success rate. Benchmark-only selection would have led to a different and worse choice.
Decision 3 — Rebuild the Compute Graph Around the Target Hardware
GR00T N1.7 baseline on IQ-9075 was 1,602.4ms. Three graph-level techniques brought it to 399.0ms:
- Vision encoder optimization distributed across multiple NPUs: approximately 60% end-to-end latency reduction.
- Operator-level graph rewriting replaced operations the IQ-9075 handles inefficiently with mathematically equivalent forms: approximately 30% reduction.
- Action head graph simplification: approximately 5% reduction.
At 399ms, the model was at the upper edge of the real-time bar with no model compression applied yet. The graph optimization work alone was sufficient to reach the threshold — which is notable, because it means model compression was needed only to reach robustly within the threshold, not to approach it.
Decision 4 — Apply Step Distillation to Reach 230ms
GR00T N1.7’s Diffusion Transformer action head generates actions through a denoising process across multiple steps. Step distillation compresses this to fewer steps without retraining the full model. Two-step distillation reached 287.4ms. One-step distillation reached approximately 230ms — a 7x improvement over the 1,602.4ms baseline — while retaining the task success rate required for real manipulation work. The accuracy loss across these steps stayed within the one-percentage-point threshold Nota had established from the backbone screening phase.
Decision 5 — Fix the Control Loop After the Model Was Done
At 230ms inference time, the arm was pausing for 501ms per cycle. The model had met its target. The bottleneck was now outside it. A profile of the control loop found that the camera thread was blocking synchronously, waiting up to 96.5ms per frame before the inference step could begin. Nota separated the camera thread to run continuously, updating a shared buffer asynchronously, and changed the control loop to read from that buffer without blocking. Frame read time dropped from 96.5ms to 0.1ms. Total observation latency fell from 700ms to 58ms. Arm idle time fell from 501ms per cycle to 247ms per cycle.
Not a single parameter of the model changed. The optimization that produced the final improvement in system throughput was outside the model entirely — it was a camera thread architecture fix.
Real-Time Chunking and the Exhibition Results
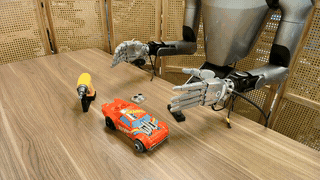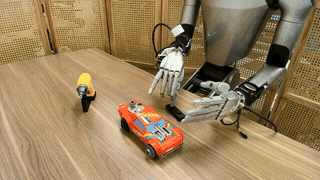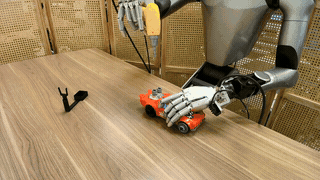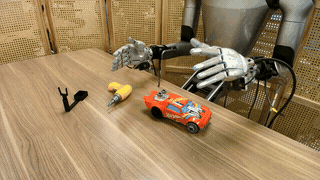
The final configuration used Real-Time Chunking (RTC): running the next inference while the previous action chunk is executing, so inference latency hides beneath the arm’s motion rather than adding to it. Over a one-hour continuous run at the exhibition, the RTC configuration achieved 37% more task completions per hour and a 21% shorter average success time compared to synchronous mode. These are the numbers from actual robot arm operation, not from simulation.
What This Means for Engineering Teams
The most portable finding from Nota’s work is that optimizing a VLA for embedded deployment is a three-layer problem: model architecture and compression, runtime and compute graph, and control loop design. Treating any one layer in isolation leaves performance on the table. Teams that optimize only the model would have missed the idle NPU. Teams that optimize only the runtime would have missed that the camera thread was the final bottleneck after the model was fast enough.
For teams building physical AI or embedded AI systems, Nota’s result establishes a concrete methodology: screen backbone models on real hardware under real success criteria before committing to optimization, rebuild the compute graph for the target NPU topology before applying model compression, and profile the full system — not just the model — after each optimization pass.
For teams working on cloud and edge infrastructure for AI deployment, the IQ-9075 result changes the deployment option space for robotics applications. Inference that required an H100 can now run on a palm-sized NPU board with commodity power requirements — with the right optimization engineering behind it. The engineering investment Nota describes (custom runtime, graph rewriting, backbone screening, step distillation) is not trivial, but it is reproducible.
Teams evaluating agentic systems that interact with the physical world should note that the control loop fix — which required no model changes and produced as much system improvement as some model optimization steps — is a reminder that AI system performance is a whole-stack problem. The agent’s intelligence does not matter if the system it operates in cannot feed it state fast enough.
Key Takeaways
- Nota AI cut GR00T N1.7 VLA inference on a Qualcomm IQ-9075 NPU board from 1,602ms to approximately 230ms — a 7x improvement — with no GPU required and less than one percentage point of task success rate degradation.
- The default inference stack left one NPU entirely idle; building a custom runtime (NQRR) that distributes the compute graph across both NPUs was the first and largest structural fix, bringing MolmoAct2 from 3,681ms to 1,173ms before any model changes.
- Backbone selection used real-hardware task success rate as a primary criterion alongside latency; the model with the lowest bare latency had the lowest physical success rate among the five candidates tested.
- Graph-level optimization brought GR00T N1.7 from 1,602ms to 399ms — within the real-time bar — before any model compression was applied.
- One-step distillation of the Diffusion Transformer action head reached 230ms; two-step reached 287ms. Both stayed within the one-percentage-point accuracy threshold.
- A camera thread architecture fix — not a model change — resolved the final system bottleneck: observation latency fell from 700ms to 58ms, arm idle time from 501ms to 247ms per cycle.
- Real-Time Chunking produced 37% more task completions per hour and 21% shorter average success time in a one-hour continuous exhibition run compared to synchronous mode.
Work With Origins AI
Origins AI builds production AI systems for engineering teams. If you are working on edge AI deployment, robot inference pipelines, or physical AI system design, talk to our team.